



A practical DIA proteomics workflow runs as matched prep (optional pressure cycling technology for tough or low-input samples), shared digestion and load QC, locked LC gradient, windowed SWATH or DIA acquisition with a documented isolation table, then library-based or library-free extraction under peptide and protein FDR control, retention-time alignment, normalization, and testing of predefined contrasts only (Gillet et al. 2012; Rosenberger et al. 2017). Lock library version, extractor settings, and window plan before scaling cohort statistics. Branch library strategy to matrix-matched DDA libraries, project-specific libraries, or defended direct DIA when library build would delay enrollment (Demichev et al. 2020). PCT-DIA is optional prep upstream of the same DIA analysis spine, not a separate quantification mode.
Researchers who already have defined samples, comparison groups, or a specific project objective can also review the MtoZ Biolabs Deep DIA Proteomics Service, Label-Free DIA Quantitative Proteomics, and DIA based Protein Quantitative Service for project-specific workflow planning.
End-to-End Workflow: Prep, Acquisition, and Analysis
PCT-DIA project records should name prep scope and DIA scope separately. Steps 1 through 4 are where PCT-DIA prep differs; steps 5 through 9 are standard label-free DIA operations (Guo et al. 2015).
- Freeze contrast arms, replicates, and the relative claim.
- Lyse and extract with conventional homogenization or a matched PCT cycle program when input or matrix requires it.
- Reduce, alkylate, digest, and clean peptides with the same recipe across groups.
- Assay protein load, pilot LC-MS when prep is new, and record batch metadata.
- Acquire DIA or SWATH windows under a locked window table, cycle time, and run-order plan.
- Convert raw files with documented centroid settings compatible with the chosen extractor.
- Extract fragment peak groups with the declared library or library-free route under FDR control.
- Align retention times, filter interfered traces, normalize, and apply a declared missing-value policy.
- Export the protein matrix and test predefined contrasts; optional PRM on a closed shortlist.
Workflow stage |
Operational deliverable |
Common pitfall |
|---|---|---|
Prep |
Matched extract and digest yields |
PCT or lysis drift across arms |
Acquisition |
Version-locked window plan |
Mid-study window changes |
Library strategy |
Documented library provenance |
Transferred library from unlike matrix |
Extraction |
FDR-controlled peak groups |
Switching extractors mid cohort |
Statistics |
Contrast-tested matrix |
Imputation before QC review |
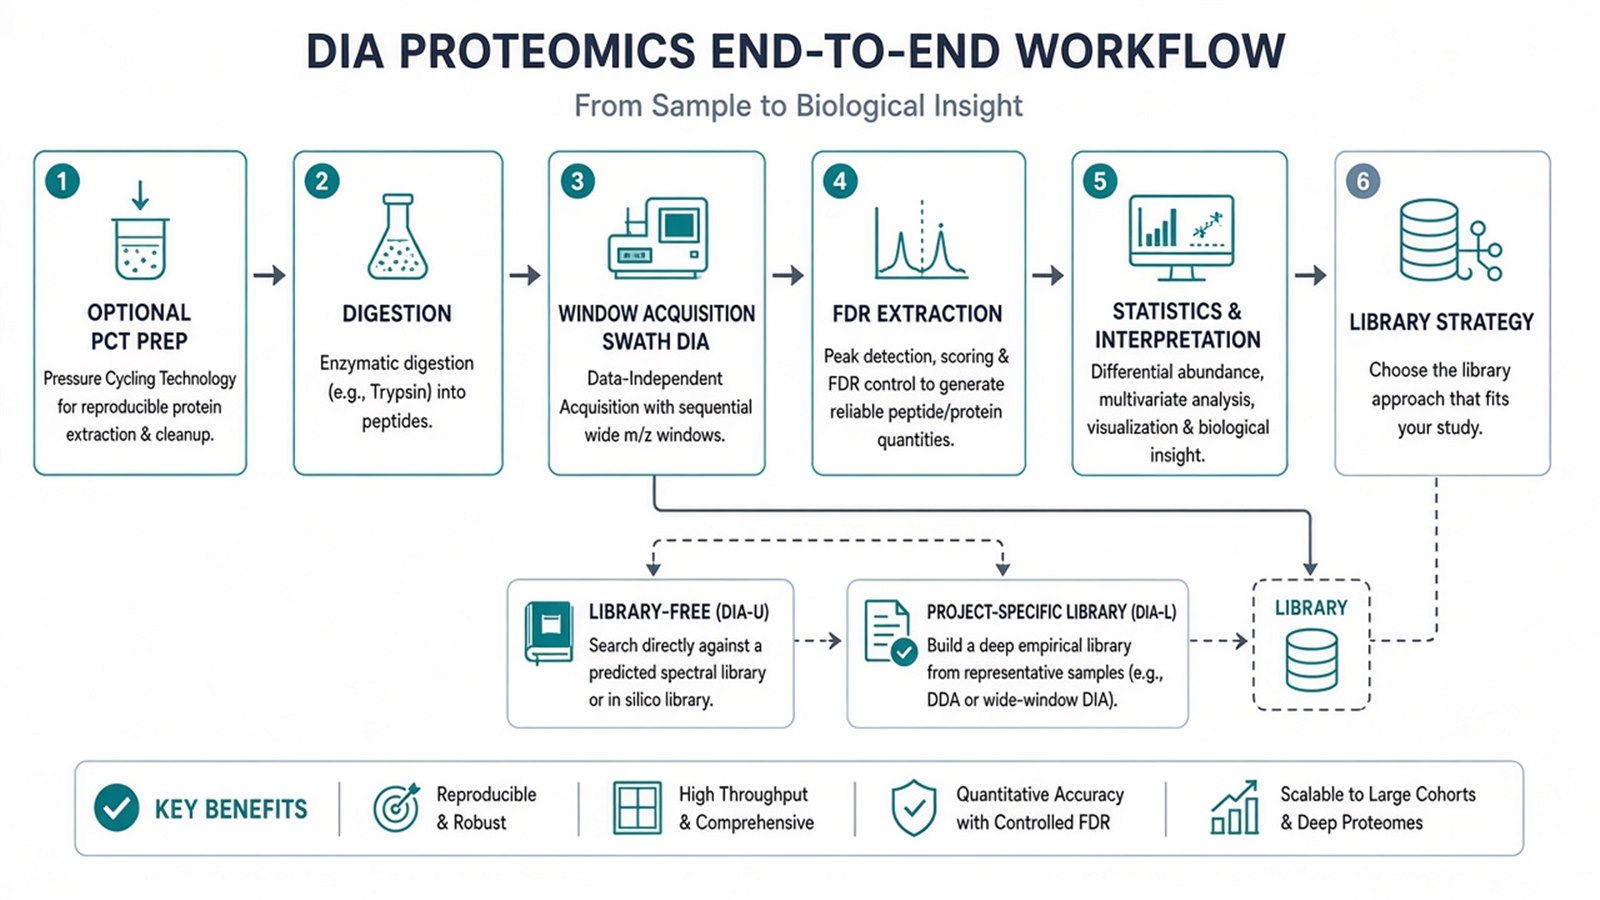
Figure 1. DIA proteomics workflow links optional PCT prep to acquisition and analysis rules that must stay version-locked across the cohort.
Merging cohorts processed under different window tables or library versions without reprocessing creates contrasts the workflow cannot defend.
For PCT-DIA definitions, see Principle of PCT-DIA Proteomics and DIA Proteomics: Principle, Workflow and Quantification Strategy. For analysis pitfalls, see SWATH-MS Data Analysis Workflow and Common Pitfalls.
Library Strategy Inside DIA and SWATH Analysis
Library choice is an analysis workflow decision, not a instrument brand choice.
Library strategy |
When it often fits |
Limit to document |
|---|---|---|
Sample-matched DDA library |
Stable matrix and time to build empirically |
Library age versus gradient changes |
Project pooled library |
Internal cohort representation |
Batch bias in pool composition |
Public or pan-species library |
Pilot feasibility only |
Missing peptides or RT drift |
Library-free or direct DIA |
New cohort, FASTA search acceptable |
Search space and interference burden |
Hybrid augment |
Extend empiric library with predictions |
Version control on additions |
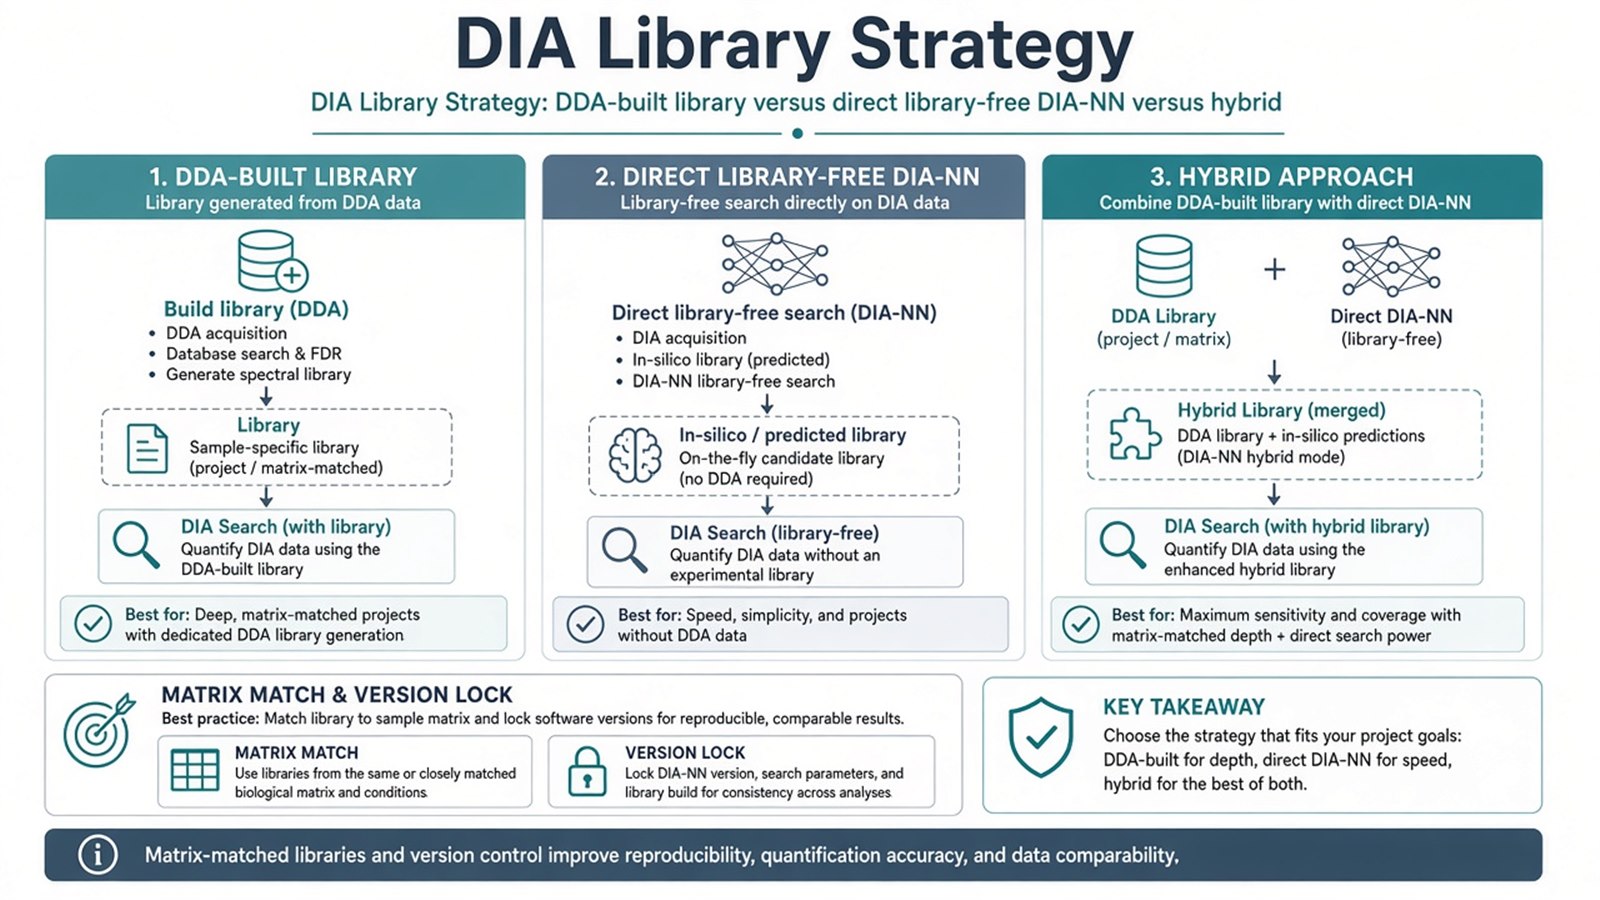
Figure 2. Library strategy determines which peptides can be extracted reliably from SWATH or DIA window files.
For methods detail, see DIA Data Analysis Methods in Proteomics and Direct DIA: High-Efficiency Proteomics Without a Spectral Library. For OpenSWATH-oriented steps, see Quantitative Analysis of SWATH Proteomics Using OpenSWATH: A Complete Workflow Overview. For application context, see Application of PCT-DIA Proteomics.
Judgment Criteria: When This DIA Workflow Fits
Study need |
DIA or SWATH workflow fits |
Reassess |
|---|---|---|
Raw data |
Scheduled-window acquisitions |
DDA MS1-only label-free files |
Prep |
Matched chemistry; PCT only if matrix needs it |
Forced PCT without prep rationale |
Library |
Matrix-matched or defended library-free path |
No FDR-controlled extraction plan |
Claim |
Relative discovery with frozen contrasts |
Diagnostic cutoff from discovery alone |
Follow-up |
Shortlist may enter PRM or AQUA |
Closed panel needs amount units now |
Prefer PCT-DIA when mechanical lysis reproducibility or low-input yield is the prep bottleneck before DIA. Prefer conventional prep plus DIA when material is abundant. Prefer TMT when same-run multiplex fits a frozen kit. Prefer PRM when targets are closed.
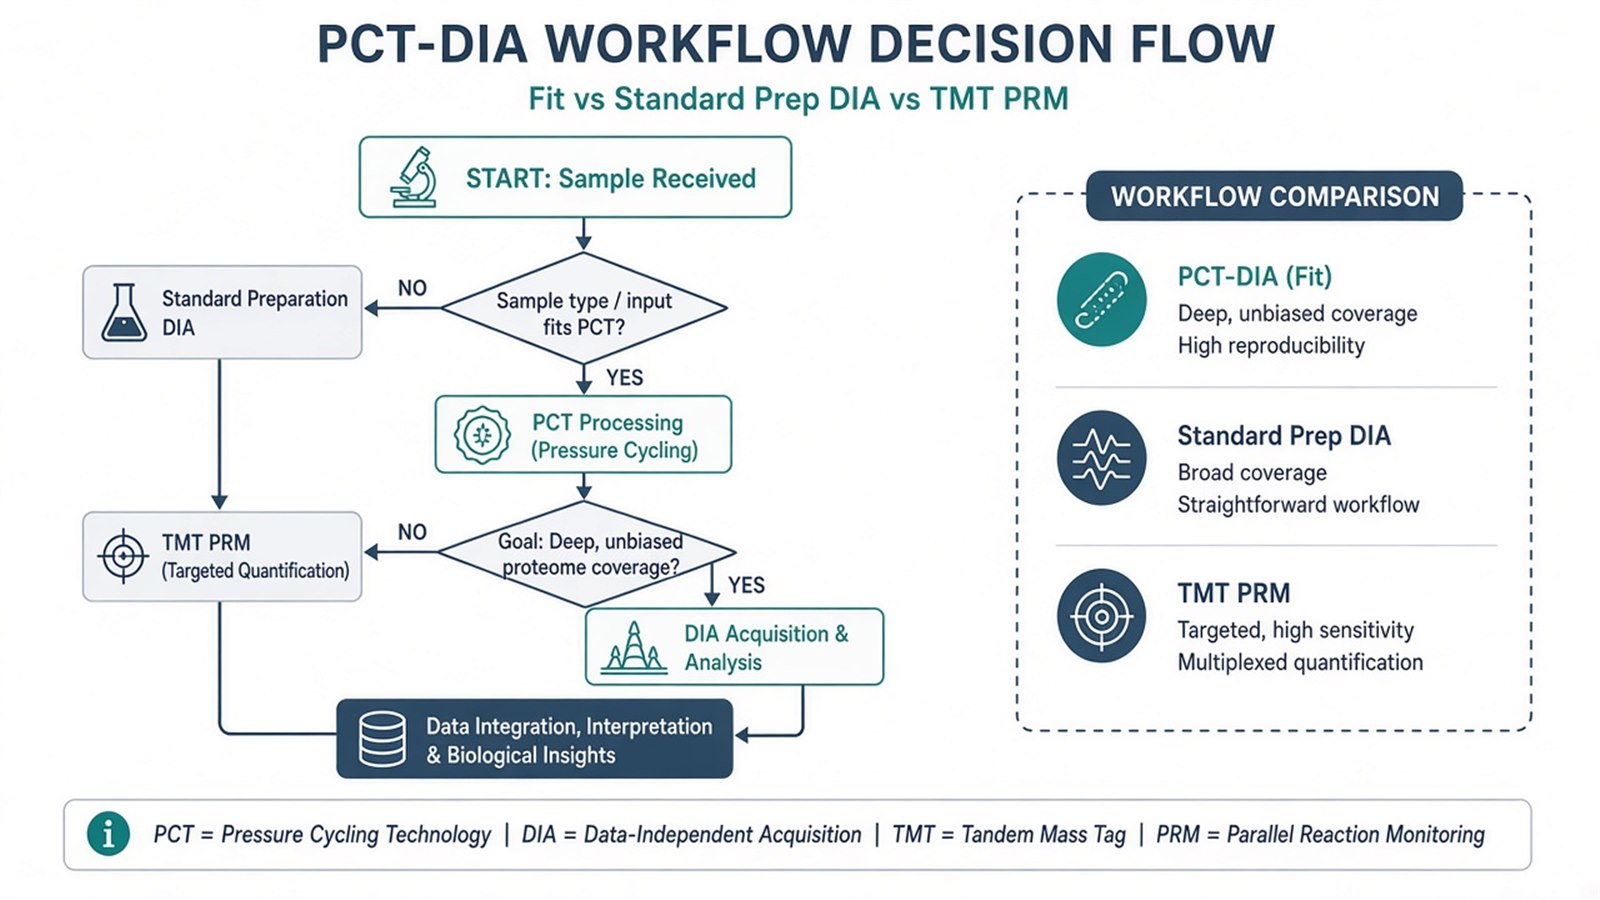
Figure 3. Choose the DIA workflow when windowed files and library strategy match the cohort; change route when labeling or targeted panels dominate.
For SWATH principle context, see Principle and Advantages of SWATH-MS Technology and Advantages and Disadvantages of SWATH-MS. For acquisition strategy, see DDA vs. DIA vs. TMT in LC-MS/MS Proteomics: How to Choose the Right Strategy.
Limits and Application Boundaries
Workflow rigor does not convert relative DIA intensities into molar concentration. PCT does not replace replicate design. Completeness after extraction is not accuracy. Batch effects from prep, PCT run day, or injection order still require documented bridges. Pathway enrichment is secondary to matrix QC. Diagnostic or personalized medicine claims sit outside ordinary research DIA reporting unless separately validated.
Typical applications after a defended workflow:
- Label-free relative discovery with optional PCT on tough or low-input material.
- SWATH cohorts with version-locked libraries and predefined contrasts.
- Biomarker nomination with planned PRM or MRM confirmation.
- Biofluid or tissue screens where windowed completeness beats DDA missingness.
- Reanalysis of stored window data under a new documented extractor version.
Once prep route, acquisition table, library strategy, and analysis version are locked, the project can deliver a traceable DIA matrix. Researchers can review the MtoZ Biolabs Deep DIA Proteomics Service for intake and analysis planning.
Frequently Asked Questions
1. Is PCT required in every PCT-DIA workflow?
No. PCT is an optional prep layer for selected matrices. DIA acquisition and analysis rules apply with or without PCT.
2. When should a project use a DDA library versus library-free DIA?
Use a matched empirical library when matrix and gradient stability support it. Use library-free routes when building a library would delay the cohort or mismatch the matrix.
3. Can window plans change mid study?
Avoid mid-cohort window changes. Treat unlike plans as separate analysis blocks or reprocess under one locked table.
4. What is the default quantitative output of this workflow?
Relative same-protein change across matched injections after FDR-controlled extraction and normalization.
5. When should DIA workflow hand off to PRM?
When a closed shortlist needs tighter fragment evidence or amount units. Discovery matrices alone do not replace targeted validation design.
Reference
- L.C. Gillet, P. Navarro, S. Tate, et al. (2012). Targeted data extraction of the MS/MS spectra generated by data-independent acquisition: a new concept for consistent and accurate proteome analysis. Mol. Cell. Proteomics, 11, O111.016717. https://doi.org/10.1074/mcp.M111.016717
- T. Guo, A. Kouvonen, P.K. Koh, et al. (2015). Rapid mass spectrometric conversion of tissue biopsy samples into permanent quantitative digital proteome maps. Nat. Commun., 6, 6690. https://doi.org/10.1038/ncomms7690
- G. Rosenberger, S. Liu, J. Röst, et al. (2017). Statistical control of peptide and protein error rates in large-scale targeted data-independent acquisition analyses. Nat. Commun., 8, 14224. https://doi.org/10.1038/ncomms14224
- V. Demichev, C.B. Messner, S.I. Vernardis, K.S. Lilley, M. Ralser (2020). DIA-NN: neural networks and interference correction enable deep proteome coverage in high throughput. Nat. Methods, 17, 41-44. https://doi.org/10.1038/s41592-019-0638-x
